Open ten data engineering requisitions this week and read the requirements line by line. Almost none of them ask for someone who owns ingestion, storage, transformation, orchestration, and serving all at once. Most are written around one layer, sometimes two, with the rest listed as 'familiarity' or 'nice to have.'
That distinction matters more than most contractors realize. If you walk into an interview claiming deep ownership of the entire pipeline, a sharp hiring manager will probe until they find the layer you actually know best and the layers you have only touched in passing. Better to know your layer cold and name it with confidence.
Here is how the modern stack breaks down, tool by tool, and which layer a contractor is typically hired to own.
1. Ingestion: Getting Data Into the System
This is the layer where data enters the warehouse or lake from source systems. Requisitions here usually name Fivetran, Airbyte, Kafka, or custom Python/API ingestion jobs.
- Fivetran / Airbyte roles are typically shorter engagements focused on connector configuration, schema drift handling, and SLA monitoring.
- Kafka-centric roles skew toward streaming use cases — fraud detection, real-time personalization — and usually sit closer to a platform or backend engineering title than a pure data engineering one.
- Custom ingestion (Python scripts hitting REST APIs, SFTP drops, CDC pipelines) still appears constantly in mid-market companies that have not standardized on a managed tool.
If your resume says 'built ingestion pipelines,' name the tool. 'Configured 40+ Fivetran connectors with custom transformation hooks' tells a recruiter something. 'Built ingestion pipelines' tells them nothing.
2. Storage: Where the Data Lives
Snowflake remains the dominant name in contract postings for warehouse storage, with BigQuery and Redshift still showing up regularly, and Databricks increasingly named for lakehouse-pattern work.
Storage-layer roles are rarely just 'storage.' They are usually bundled with cost optimization, access control, and schema design. A requisition naming Snowflake specifically is often looking for someone who can:
- Design warehouse sizing and auto-suspend policies to control compute cost
- Implement role-based access control and row-level security
- Manage Snowpipe or external stages for continuous loading
This is not the same skill set as dbt modeling, even though the two frequently appear in the same posting. Storage administration and transformation logic are adjacent, not identical.
3. Transform: dbt and the Modeling Layer
dbt has become the de facto standard for the transform layer, and it shows up in job titles now, not just requirements lists — 'dbt developer' is a real posting title, not shorthand.
This layer is about writing and testing SQL models, managing a DAG of dependencies, and enforcing data quality through tests and documentation. A contractor hired for this layer should be fluent in:
- dbt model structure (staging, intermediate, marts)
- Jinja templating and macros
- dbt tests, including custom singular tests
- Git-based CI workflows for dbt projects
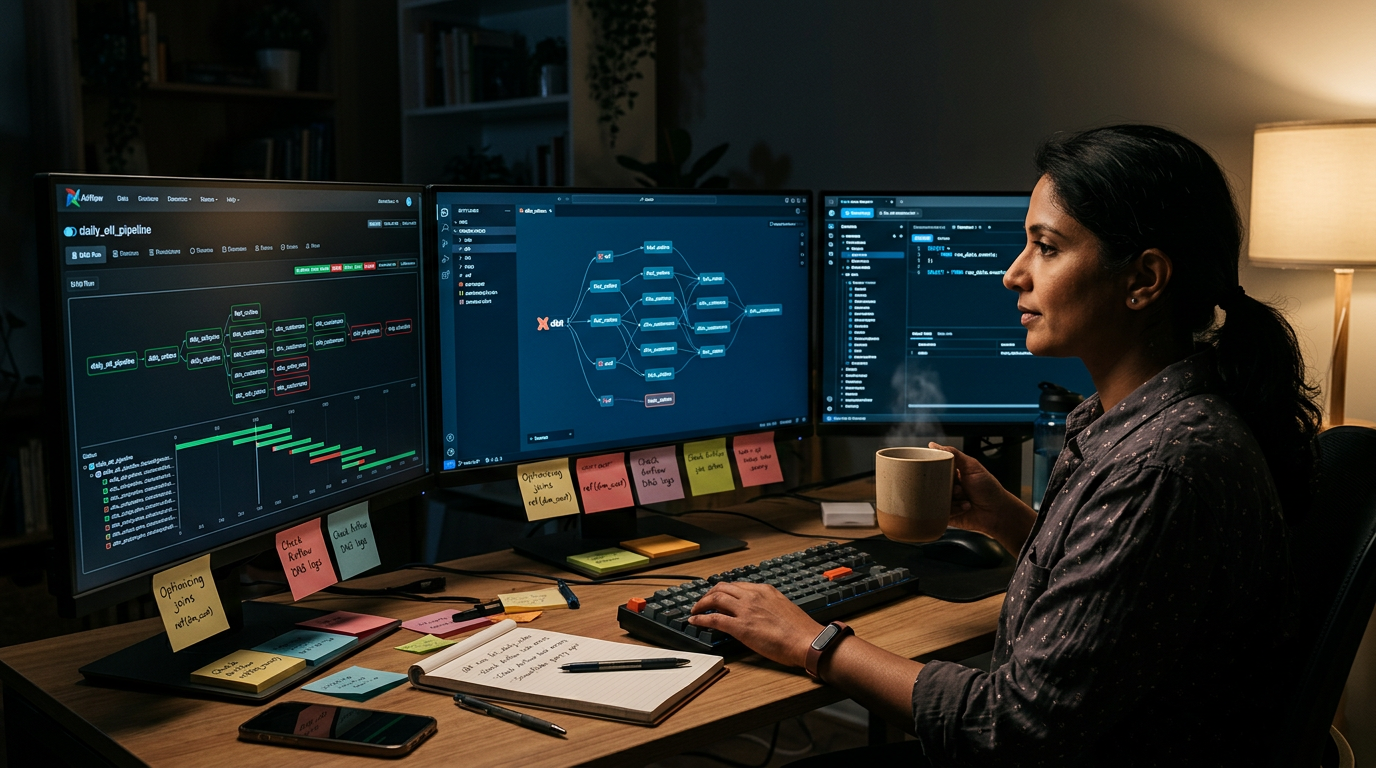
This is frequently the single most in-demand layer for pure contract work because it is self-contained. A client can hand you a dbt project, a Snowflake connection, and a backlog of broken models without needing you to touch ingestion or orchestration at all.
4. Orchestration: Airflow and the Scheduling Layer
Airflow remains the most-named orchestrator in postings, with Dagster and Prefect appearing in smaller but growing numbers, particularly at companies that adopted them after 2022.
Orchestration roles are about DAG design, dependency management, retries, alerting, and backfills — not writing the transformation logic itself. A common mistake is a dbt specialist assuming Airflow experience because they used the dbt-Airflow integration. Owning the orchestration layer means you can debug a stuck DAG, manage Airflow's metadata database, and tune worker concurrency at 2 a.m. when a pipeline fails before a board meeting.
Quick Reference: Layer-to-Tool Mapping
| Layer | Commonly Named Tools | Typical Contract Focus |
|---|---|---|
| Ingestion | Fivetran, Airbyte, Kafka | Connector config, streaming pipelines, CDC |
| Storage | Snowflake, BigQuery, Databricks | Schema design, access control, cost tuning |
| Transform | dbt | SQL modeling, testing, documentation |
| Orchestration | Airflow, Dagster, Prefect | DAG design, scheduling, alerting |
| Serving | Looker, Tableau, reverse-ETL tools | Semantic layer, dashboard delivery, API exposure |
5. Serving: Where Data Meets the Business User
The serving layer is the least uniform across postings because it depends entirely on who consumes the data. Looker and Tableau dominate when the audience is business analysts. Reverse-ETL tools like Hightouch or Census show up when the destination is a CRM or marketing platform rather than a dashboard.
Contractors hired for this layer are rarely deep SQL engineers. They are closer to analytics engineers — people who understand the semantic layer, can build a LookML model or a Tableau data source, and can translate a stakeholder's vague request into a defined metric.
Positioning Yourself for One Layer
The practical move tonight is simple: pick the layer where your last two contracts actually lived, and rewrite your resume summary around that layer's vocabulary. If your last two roles were dbt-heavy, lead with dbt model counts, test coverage improvements, and CI pipeline changes — not a vague 'full-stack data engineer' label.
If you genuinely have cross-layer experience, list it as a secondary strength, not the headline. A posting that names Snowflake, dbt, and Airflow in the same paragraph is usually describing a team's stack, not a demand that one person own all three equally.
Honest layer-specific positioning also changes the kind of client conversations you get. You stop being screened against a generalist bar and start being compared against specialists — a fight you are far more likely to win if you have actually spent 18 months inside one layer rather than six months each across four.
If you want a second opinion on which layer your resume currently signals, the team at Josh Pros LLC reviews consultant resumes against live requisition language every week. Email contact@joshpros.com or visit https://joshpros.com and we will tell you, plainly, what a hiring manager will think you own.
#DataEngineering #SnowflakeDbtAirflow #DataEngineerSkills2026 #ContractDataJobs #dbt #ApacheAirflow #SnowflakeCareers #DataPipelineSkills #TechContracting #ITStaffing #DataEngineerResume #ModernDataStack
Talk to a real recruiter, not a bot.
We'll tell you the rate, the client, and the terms before you interview. And if we're not the right fit, we'll say so.